WordOnThis

Compare speech-to-speech models on live phone calls

The overview

What is Cekura Bench?

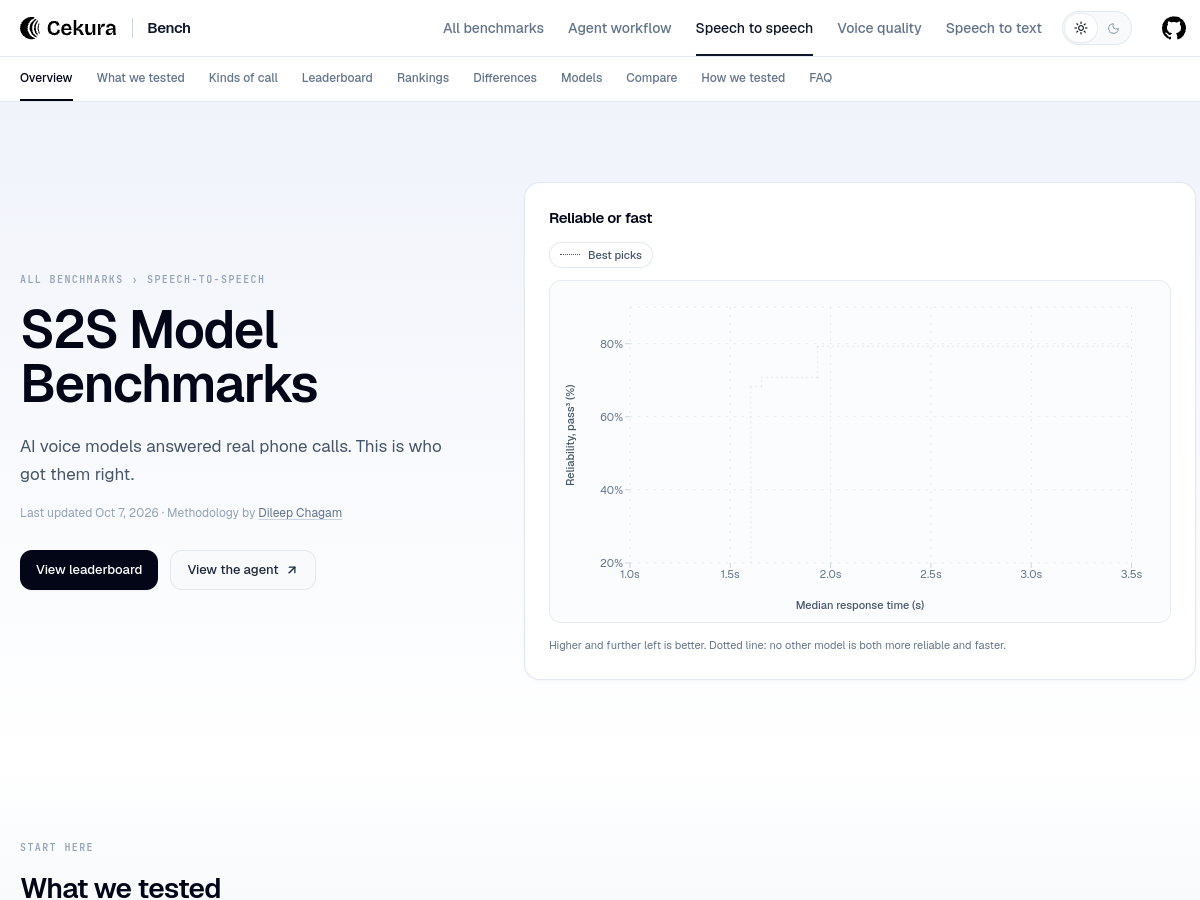
Cekura Bench is a benchmarking feature for comparing speech-to-speech models in live phone-call scenarios. It gives voice AI teams a way to evaluate models under conversational conditions. The feature is part of Cekura, a broader platform for testing and monitoring voice and chat agents across development and production.
Cekura Bench screenshot 1

Around the internet

What people are saying

Public experiences, questions, and discussions.

No discussions collected yet.

Inside the toolkit

Key features

Benchmark speech-to-speech models

Test and compare speech models on the same phone-call scenarios, including healthcare appointments and Medicare intake.
Compare reliability, speed, and cost

The leaderboard reports repeat-run reliability, success rate, data accuracy, stalled calls, response time, and cost per minute.

Filter and inspect rankings by scenario

Filter the leaderboard by suite or call type and open a model for its detailed results.

Public methodology and benchmark data

The site links test cases, agent definitions, benchmark code, recordings, and downloadable JSON data.

Where it fits

Use cases

  • Compare speech-to-speech modelsCompare models on the benchmark’s clinic and Medicare call scenarios using reliability, response time, and published cost.
  • Evaluate healthcare phone workflowsReview results for appointment booking, changes, cancellations, and Medicare information collection and routing.
  • Review how benchmark results were producedInspect the published method, cases, code, and recordings behind the rankings.

Keep exploring